TLDR;
When you fire up a copy of VSCode and connect it to any of the usual AI suspects … it’s kinda magical. Ask it to draft a plan to build X, and then you get a pagefull of X, and then y,z + a+b+c. All using highly technical language and nice diagrams, even psuedo code.
Then you prompt: “now pls implement”
10 min of text scrolling by … and voila! You’ve got about a weeks worth of coding!
This is REALLY cool.
But what’s actually happening here? How do we go from “a really good text extrapolation engine” to something that feels like an SDLC?
Let’s dive into the basic parts to get a better understanding …
text in / text out
At its core, all ai is just a really well-tuned LLM. What’s that? Probaly too much to unpack there. Just know its a neural network thats been tuned to take text in and generate text out.
location, location, location
TLDR; context, context, context!
Given that the llm merely does text in / text out, we need to ensure that text in has all the pertinent information.
But what does that mean?
We need to ensure that we’ve framed the question or directive appopriately. e.g. The high level must be stated in breif, concise terms. Concurrently, we need to include specifics. Kinda sounds like having cake and eating it too, right?
So here’s a simple flow to illustrate the point:
#!/usr/bin/env python3
import os
import sys
from groq import Groq


api_key = os.environ.get("GROQ_API_KEY")
if not api_key:
    print("ERROR: GROQ_API_KEY environment variable not set.")
    sys.exit(1)


client = Groq(api_key=api_key)
model_name = "qwen/qwen3.8-27b"
prompt = sys.argv[1]

messages = [
    {
        "role": "user",
        "content": f"{prompt}",
    },
]

print("-- BEGIN PROMPT\n")
print(f"{messages}")
print("-- END PROMPT\n")


res = client.chat.completions.create(model=model_name, messages=messages)

print("-- RESPONSE:")
print(f"{res.choices[0].message.content}\n\n")
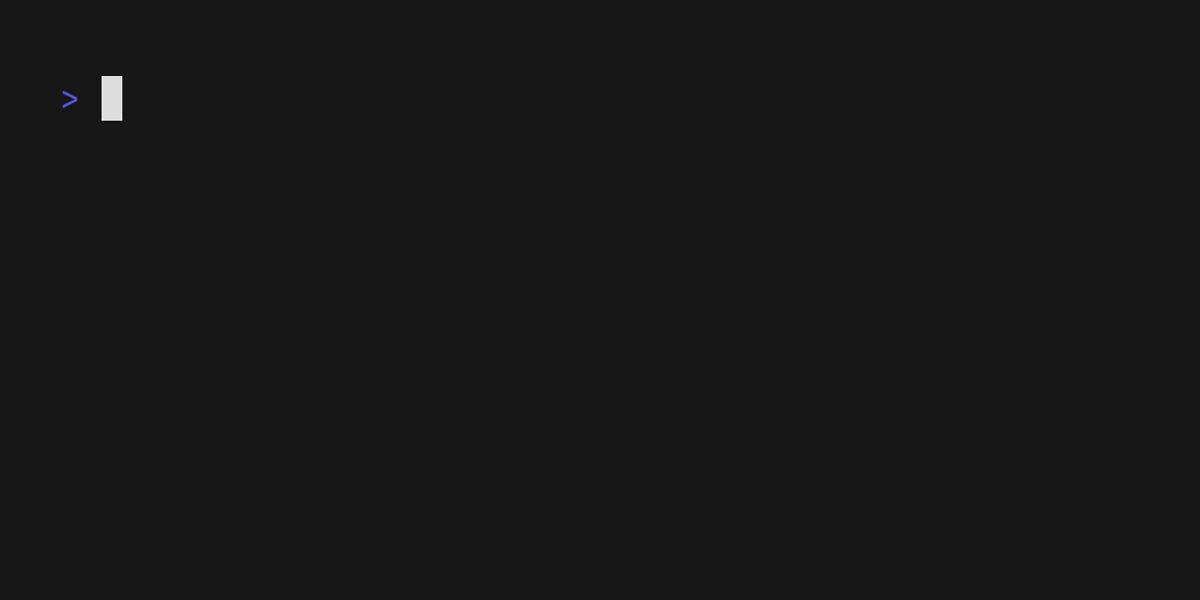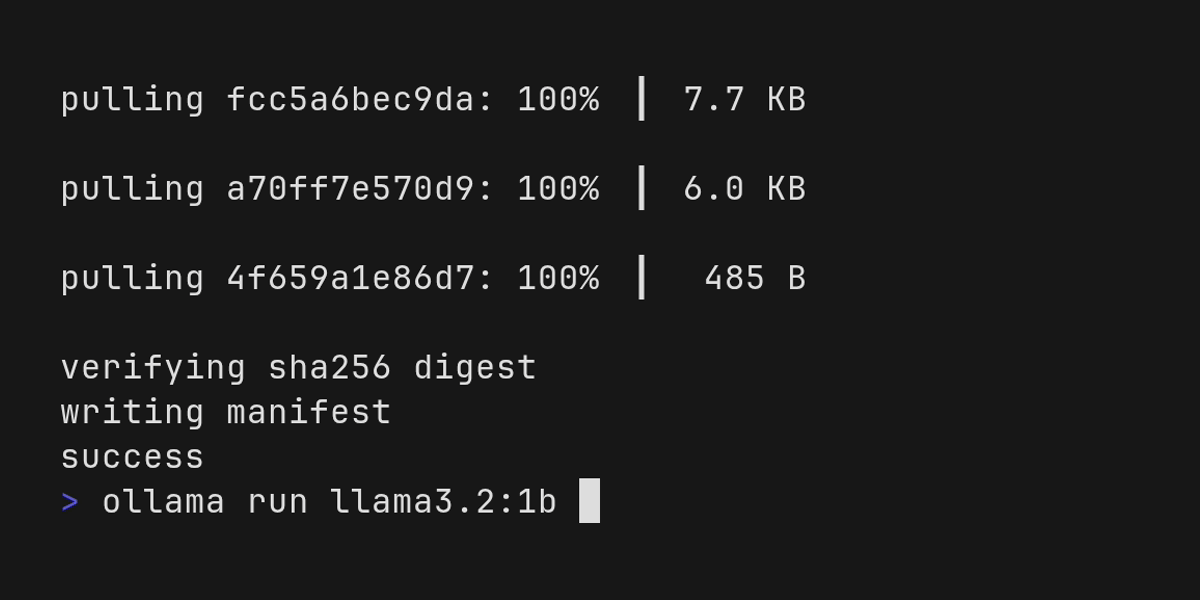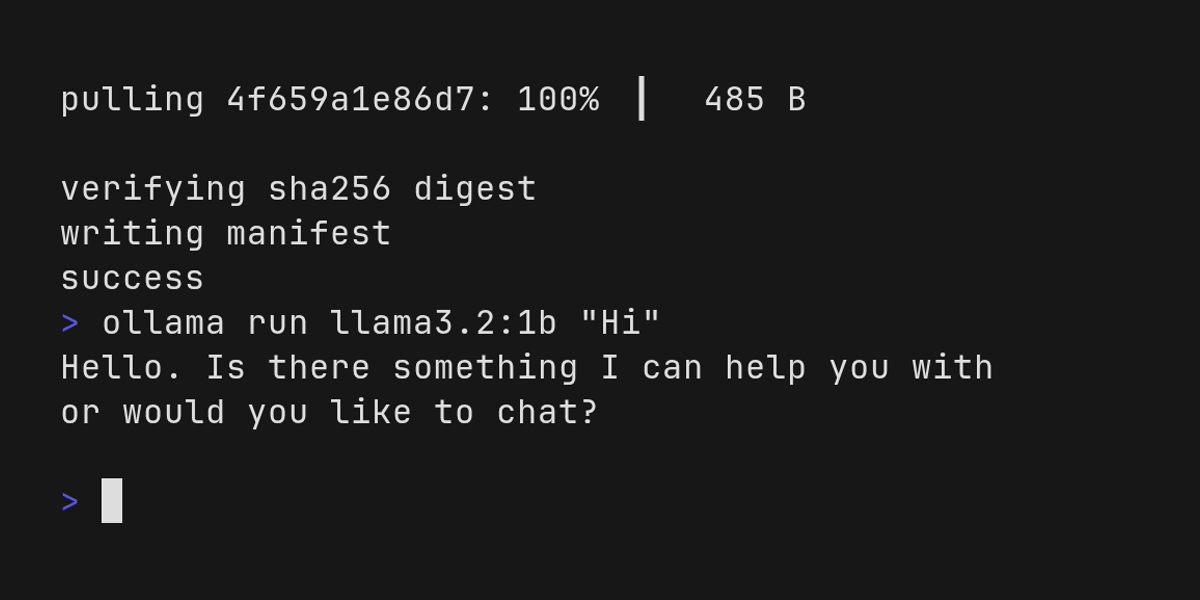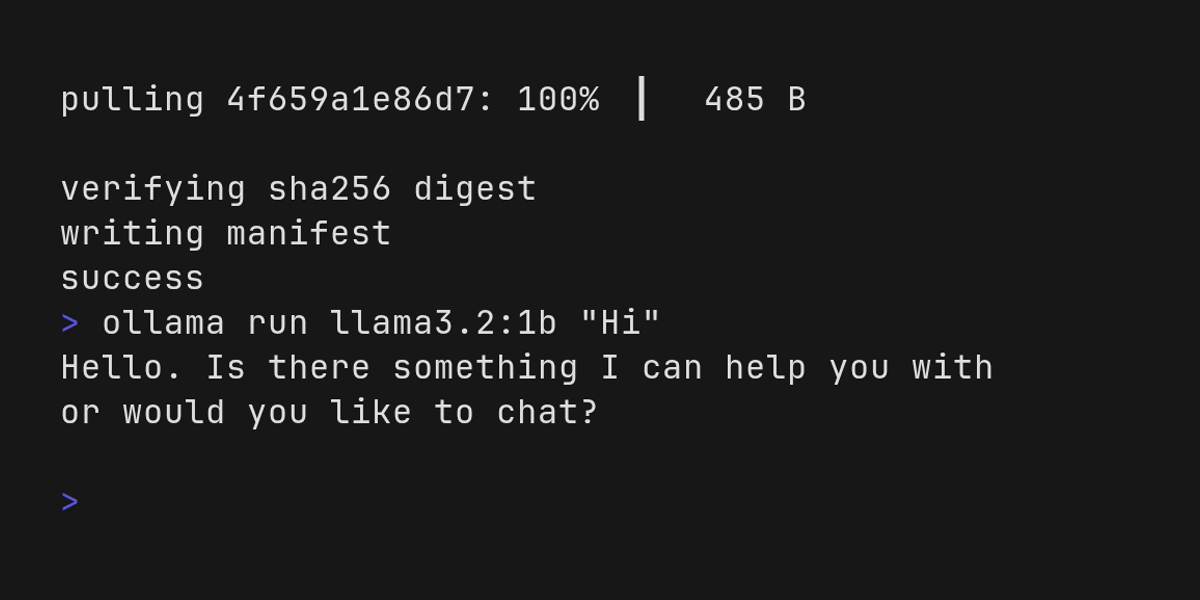
Context-Free Chat
e.g. just say “Hi” and here’s what we get:
Cha with Flair
Let’s inject some context. aka a system prompt.
e.g. just say “Hi”, but also we’re talking to Hal: